Own the Voice Pipeline
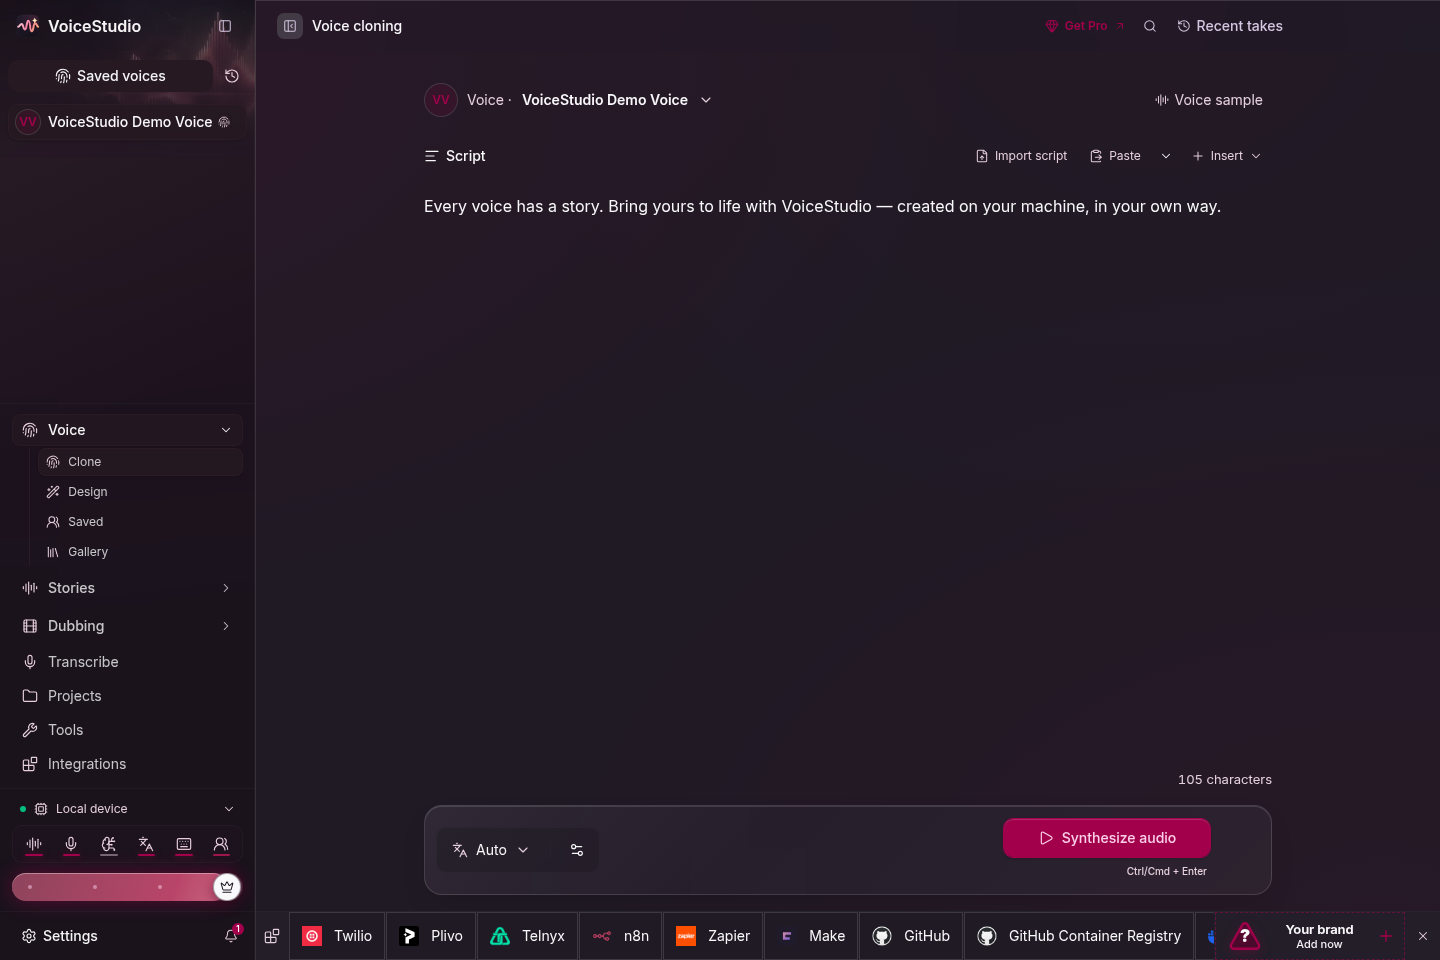
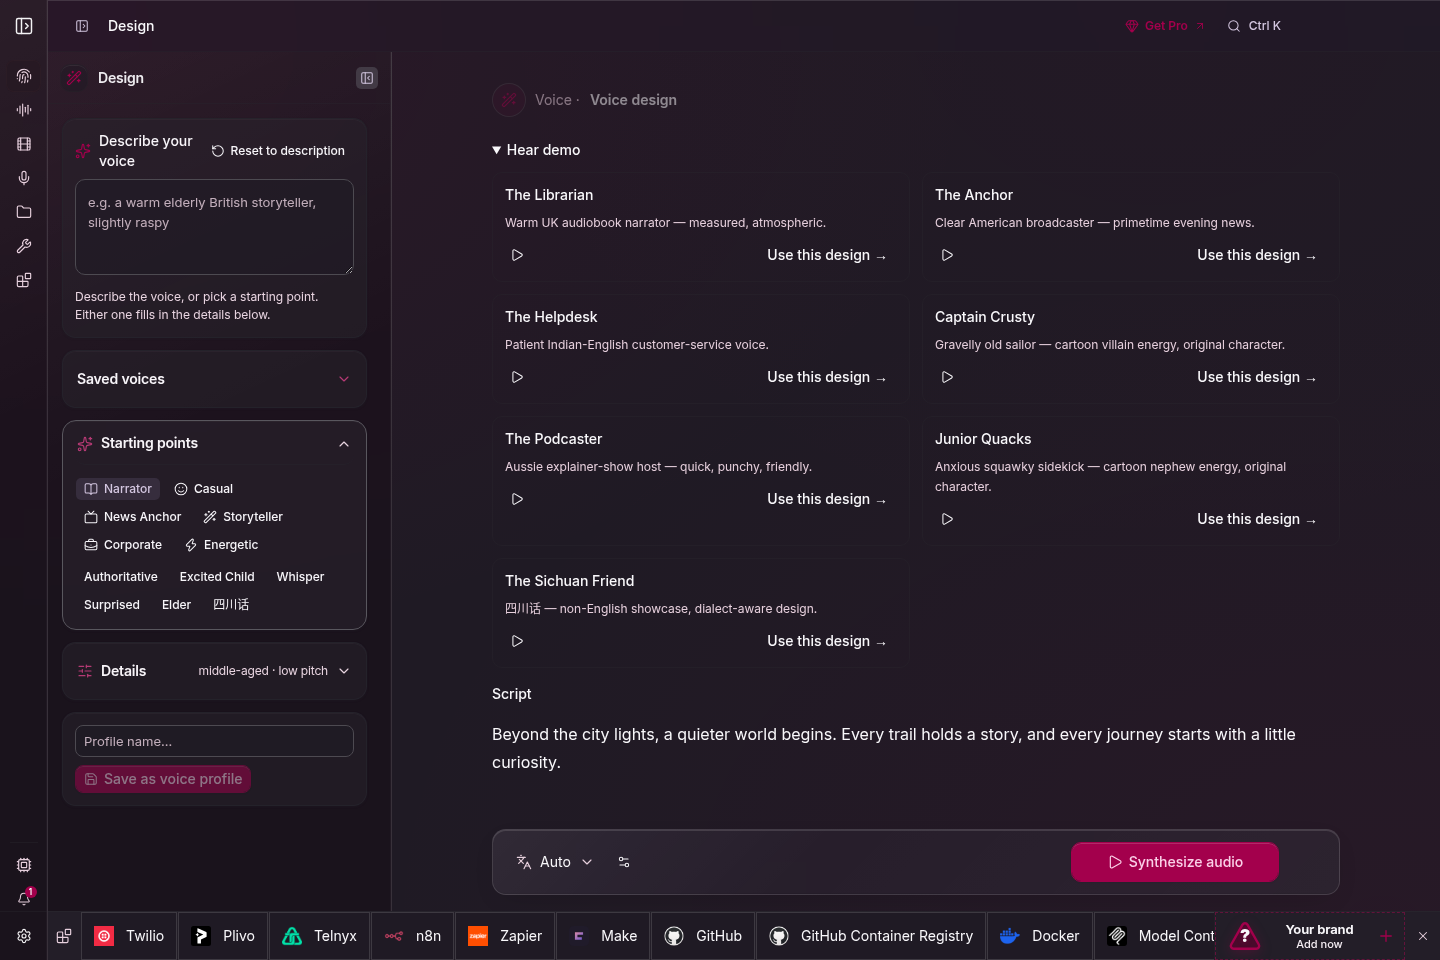
Clone, design, generate, dub, and dictate from one desktop studio, with the models and output under your control.
 VoiceStudio.sh
Make voices. Tell stories. Keep the files.
Clone, design, dub, dictate, and build audiobooks in one open-source desktop studio. Local-first by default — no subscription, no usage meter; online services stay opt-in.
Clone, design, generate, dub, and dictate from one desktop studio, with the models and output under your control.
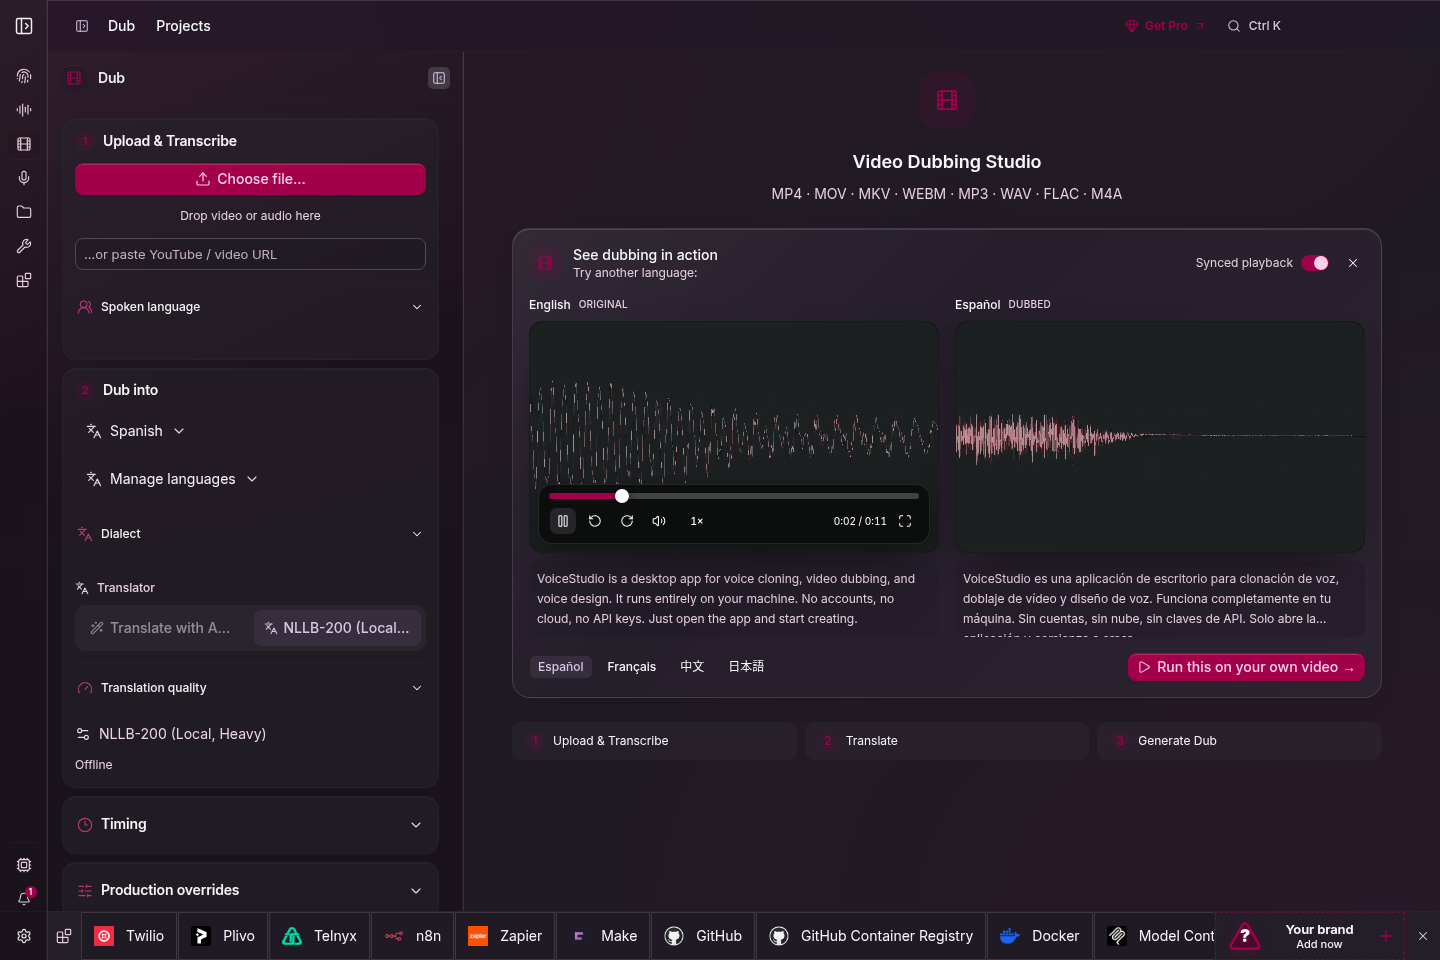
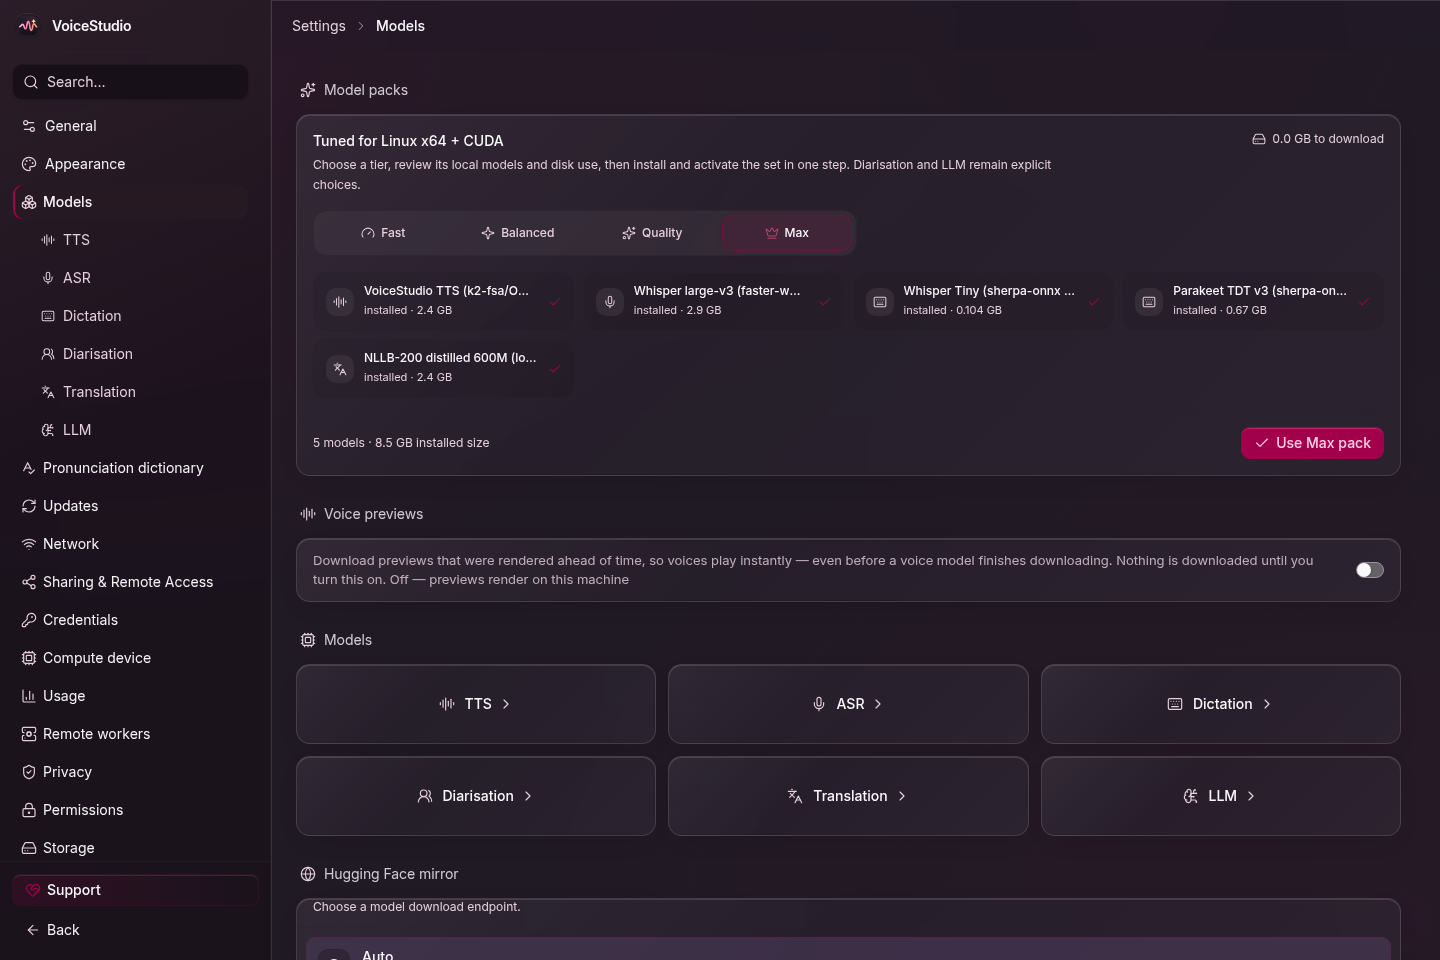
A multi-track dubbing workflow, audiobook editor, project library, voice gallery, and engine controls turn isolated model demos into repeatable work.
Use MLX on Apple silicon, CUDA on NVIDIA, ROCm on Linux, Docker on a server — or the OpenAI-compatible API from another tool.
Same jobs, different terms. This is the table that made me build it.
| ElevenLabs | VoiceStudio | |
|---|---|---|
| Pricing | Subscription + usage meter | Free, open source — AGPL-3.0 |
| Voice cloning | 3s clip | 3s clip, zero-shot |
| Voice design | Gender, age | Gender, age, accent, pitch, style, dialect |
| Audiobooks | — | Full editor — EPUB/PDF in, .m4b out |
| Languages | Plan-dependent | 646 |
| Video dubbing | Cloud-only | Fully local |
| Where audio goes | Their servers | Your machine — online is opt-in |
| API keys | Account required | None for local work |
| GPU | N/A — it's a browser tab | CUDA · Apple Silicon · ROCm · CPU |
| Desktop app | — | macOS · Windows · Linux |
| TTS engines | 1 | 16 |
| ASR engines | 1 | 11 |
| MCP server | — | Claude, Cursor, any MCP client |
| Source | Closed | Fork it, extend it, ship it |
A GPU is optional. The whole pipeline runs on CPU — slower, but yours.
| Minimum | Recommended | |
|---|---|---|
| OS | Windows 10 · macOS 13.3+ (Apple Silicon) · Ubuntu 24.04+ | Any modern 64-bit OS |
| RAM | 8 GB | 16 GB+ |
| VRAM | 4 GB — TTS auto-offloads to CPU | 8 GB+ (RTX 3060+) |
| Disk | 10 GB free | 20 GB+ SSD |
| GPU | Optional — CPU works | NVIDIA CUDA · Apple MPS · AMD ROCm (Linux) |
One picker, Cmd/Ctrl+E from anywhere. Defaults are chosen; the rest auto-detect or install on first use.
| Count | Default | Standouts | |
|---|---|---|---|
| TTS | 16 | VoiceStudio — 600+ languages, clone + instruct | CosyVoice 3 · VoxCPM2 · IndexTTS 2.5 · MLX-Audio on Apple Silicon |
| ASR | 11 | WhisperX — ~100 languages, word-level timing | Parakeet TDT at ~10× realtime on CPU · FunASR with inline diarization |
Drop-in OpenAI/ElevenLabs-compatible API: point your existing SDK at localhost — voice takes your own cloned-profile IDs, model pins an engine per request.